
Find it in Reporting > Dashboards > AI agents overview, in a weekly or a monthly view. Below are answers to the questions that come up most often once people start reading it.
For request, SLA, and export metrics, see Understanding our dashboards and analytics.
Scope and filters
What counts as a conversation?
A conversation is one exchange between an employee and the AI Agent, from the employee's first message until the conversation ends. It ends because they got their answer, because a support request was created, or because they simply stopped replying.
Every rate on the dashboard uses the number of conversations in the period as its denominator, unless stated otherwise. Conversations are dated by when the conversation started, not by when a request was later created from it.
Which conversations do I see?
The same permission logic as every other Siit dashboard. You see conversations whose resulting request you have access to, because you are the assignee, it sits in one of your inboxes, you are a follower, or your role grants access to all requests.
Two admins can legitimately see different numbers on the same dashboard. Check your request permissions if a figure looks lower than you expect.
What does each filter do?
| Filter | What it filters on |
|---|---|
| Date | The date the conversation started |
| Service | The service of the request that came out of the conversation |
| Inbox | The inbox the resulting request was assigned to |
| Channel | Where the conversation took place: Slack, Microsoft Teams, or the Portal |
| Article suggested category | The category of the article the agent recommended |
Why did my numbers change after I filtered on a service or an inbox?
Service and Inbox both describe the resulting request. A conversation that ended without a request has neither, so applying either filter narrows the dashboard down to escalated conversations only.
Expect deflection rate to fall close to 0% and escalation rate to climb close to 100% while one of those filters is on. That is the filter doing its job. Those two rates are not meaningful in that state, so read the tables rather than the headline rates.
Why don't the adoption tiles react to my filters?
The two adoption tiles and the adoption chart respond to the Date filter only. Agent, Service, Inbox, Channel, and Article suggested category do not apply to them, because they are computed over all requests rather than over agent conversations.
Reading the rates
Why is my deflection rate lower than my article suggestion rate?
This is always expected. Suggesting an article is necessary but not sufficient. The employee still has to accept it and not create a request.
The gap between the two is exactly the population worth investigating, and it is what the Escalated despite an article suggestion table lists.
Why don't suggestion, deflection, and escalation add up to 100%?
Because they are three separate questions asked of the same conversations, not three slices of a pie. A single conversation can land in more than one, or in none:
| What happened | Where it counts |
|---|---|
| Article suggested, request created | Suggestion rate and escalation rate. Not deflection. |
| Article suggested, employee rejected it, no request | Suggestion rate only. |
| Nothing suggested, no request | None of the three. Mostly unresponsive users. |
What does a low article suggestion rate mean?
Usually a knowledge base gap rather than an agent problem. The agent can only recommend what exists. The Escalated with no article suggested table names the exact questions you have no answer for.
Is a high escalation rate a bad sign?
Not on its own. Plenty of requests have to reach a human: an approval, an access grant, a hardware order. What matters is escalation on topics your knowledge base should already cover, which is what the Escalated despite an article suggestion table isolates.
Can I compare the weekly and monthly dashboards directly?
Yes. The metrics are defined identically on both. Weekly figures on a low volume workspace are noisy, so if a single week holds fewer than about 30 conversations, read the monthly dashboard instead.
Use the weekly view to watch the effect of a change you just made, such as a new article or a reworded agent instruction. Use the monthly view for trends and anything you plan to present.
Employee behaviour
What does the unresponsive user rate tell me?
It counts conversations where no request was created and the last message was the agent's. The agent said something, and the employee never came back.
This is the dashboard's ambiguity metric. Some of these are silent successes, and some are silent failures where the employee gave up and asked a colleague instead. Watch it as a trend rather than an absolute:
- Unresponsive down while deflection is up. The agent is closing conversations properly.
- Unresponsive up while deflection is flat. Employees are disengaging. Check the messages before drop-off.
What does "average messages before a user drops off" mean?
Among unresponsive conversations only, the average number of messages the employee sent before going quiet.
- 1 message. They asked once, did not like the reply, and left. Usually an answer quality problem.
- 4 or more. They genuinely tried. A frustrating experience, and a strong candidate for a new article or a sharper agent instruction.
What does "average messages before a request is created" mean?
For escalated conversations only, the average number of messages the employee sent before the request was created, broken down by the service of that request. Read it as a friction score.
- High. Employees go back and forth before giving up. The agent is hesitating on this topic, or the articles it finds are near misses.
- Low, 1 to 2. The agent escalates almost immediately. Correct for services that always need a human, but worth checking it is not skipping a perfectly good article.
Knowledge base
How do I read the Article performance table?
One row per help article the AI Agent recommended during the period.
| Column | Meaning |
|---|---|
| Nb suggested | How many conversations the article was recommended in |
| Nb deflected | Of those, how many ended with no rejection and no support request |
| Nb approved | How many times the employee explicitly confirmed it answered them |
| Deflection rate | Nb deflected divided by Nb suggested |
| Last time used | The most recent conversation the article was suggested in |
Three patterns are worth acting on:
- High suggested, low deflection. The agent keeps reaching for this article and it keeps failing. Rewrite it, or it is being matched to the wrong questions.
- High suggested, high deflection. Your best article. Use it as the template for the rest.
- An old "Last time used". The article has stopped being relevant, or newer ones now outrank it.
What is Article category performance for?
It aggregates the same picture by category, so you can see which domains of your knowledge base (People, IT, Finance) are carrying conversations and which are being rejected. Use it to decide where to invest documentation effort, then drop into the article level table to decide what to write.
What should I do with the two tables at the bottom?
Treat them as your documentation backlog. Both list real conversations with the employee's first message and a direct link to the request that was created.
- Escalated despite an article suggestion. The knowledge base had something, but it was not good enough. These are rewrite candidates, and each row names the article that failed.
- Escalated with no article suggested. The knowledge base had nothing. These are new article candidates, and the highest leverage list on the dashboard.
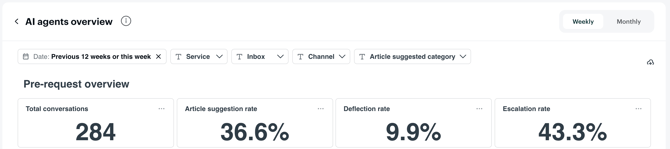
- Total conversations. Number of AI Agent conversations started in the period.
- Article suggestion rate. Percentage of conversations where at least one help article was recommended.
- Deflection rate. Percentage of conversations where an article was recommended, not rejected, and no request was created.
- Escalation rate. Percentage of conversations that resulted in a support request.
- Requests created via the AI Agent. Percentage of all requests that came from an AI Agent conversation.
- Employees using the AI Agent. Percentage of requesters who created at least one request via the AI Agent.
- Unresponsive user rate. Percentage of conversations that ended with the agent speaking last and no request created.
- Average messages before drop-off. Average employee messages in those unresponsive conversations.
- Article deflection rate. Per article, the percentage of its suggestions that ended without rejection and without a request.